EC-VLMEmergent Corpus Pre-training Benefits Vision Language Models

●Virginia Tech♦︎PLAN Lab · University of Illinois Urbana-Champaign

TMLR 2025

TL;DR

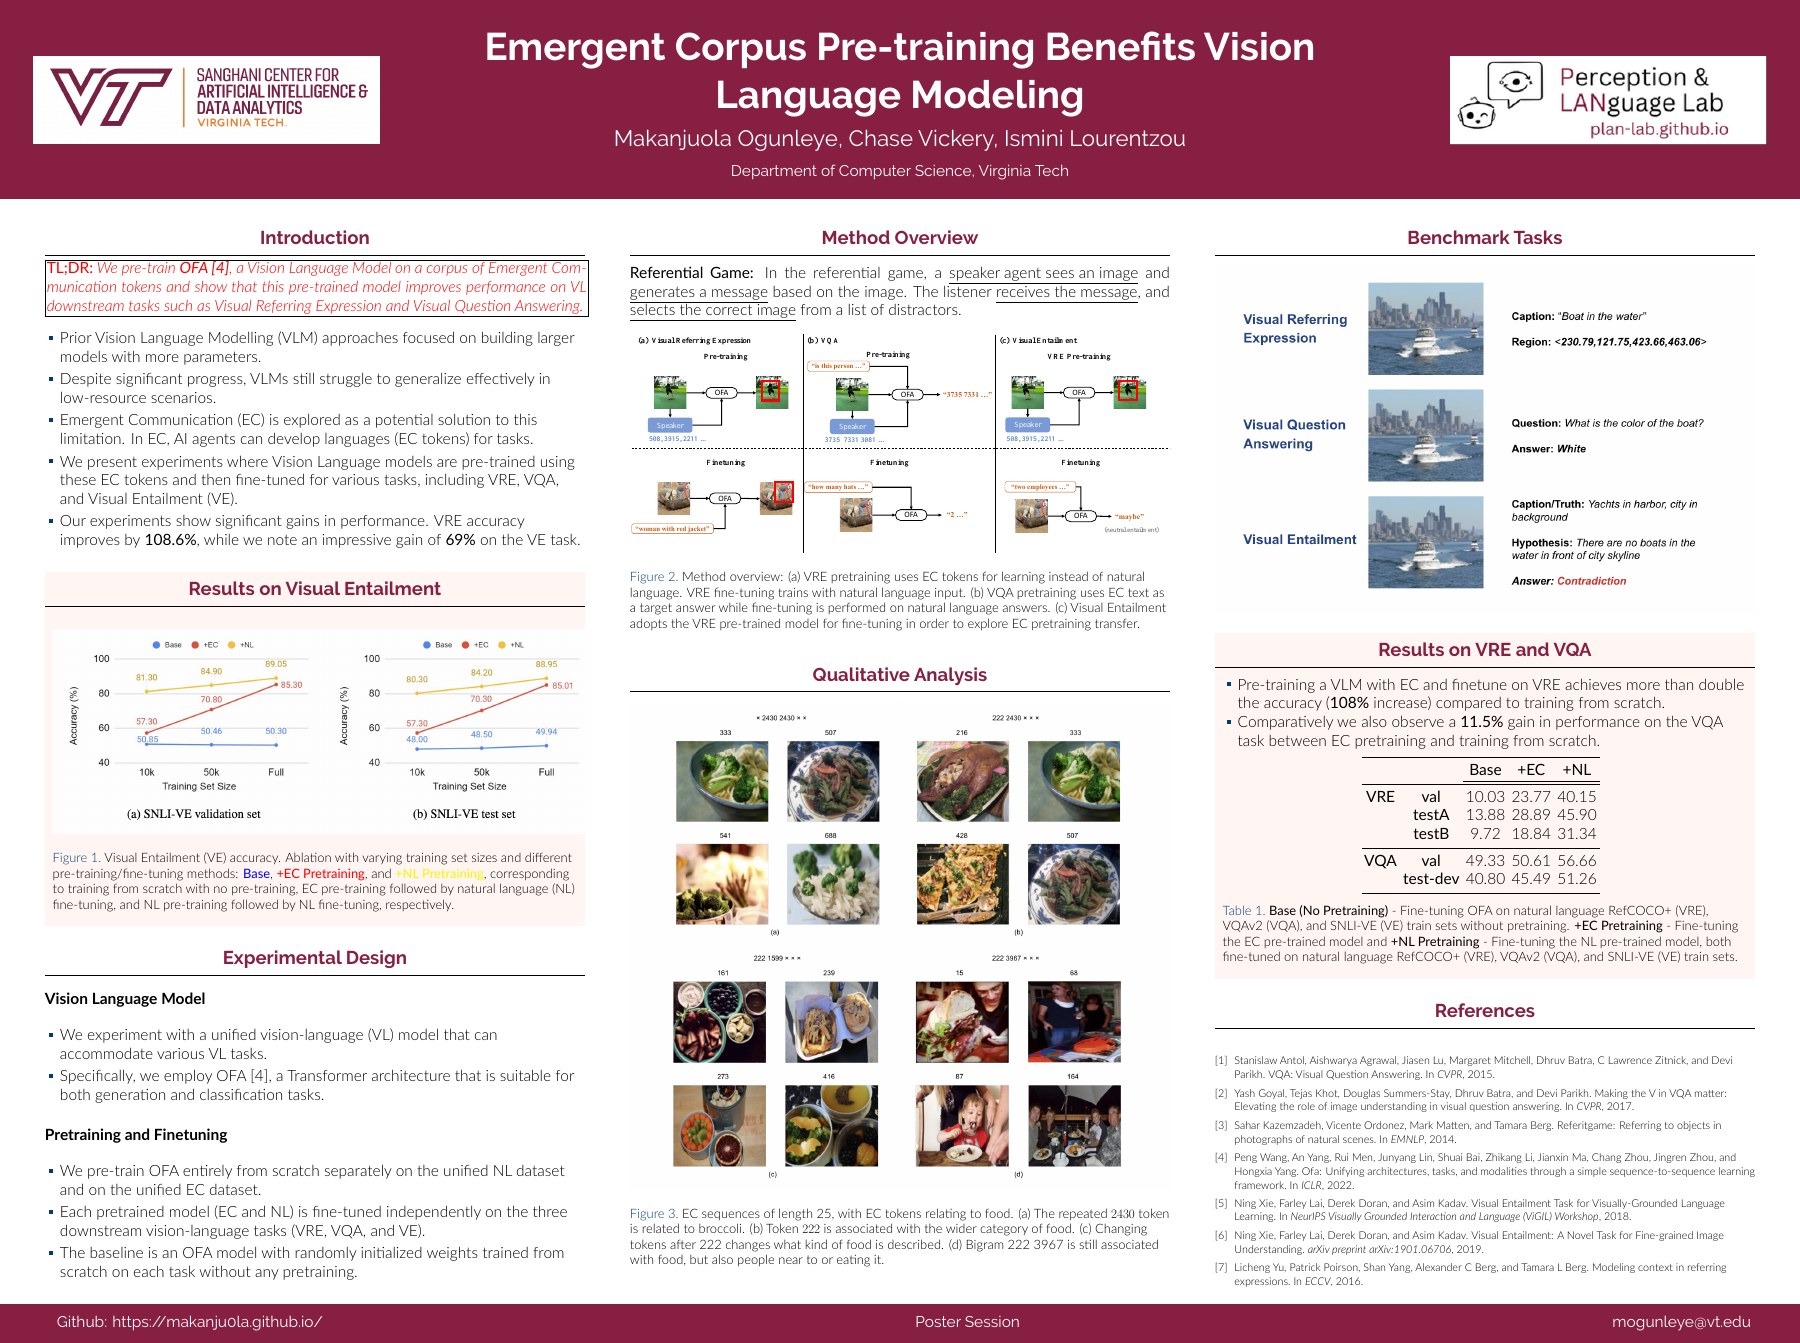
We introduce EC-VLM, a framework that uses communication between artificial agents to pretrain vision-language models. Messages learned in an image-based speaker–listener game provide visual supervision that transfers to tasks such as captioning, question answering, and referring-expression understanding.

A speaker generates image-grounded EC messages; a listener identifies the target image. These messages pretrain a VLM for downstream vision-language tasks.

Emergent communication for vision-language pretraining

Left: a speaker describes a target image with learned EC tokens, and a listener selects that image among distractors. Center: image–message pairs pretrain a vision-language model. Right: visual grounding transfers to entailment, captioning, referring expressions, and question answering.

Abstract

Vision-Language Pre-trained Models (VL-PTMs) have achieved impressive performance across a wide range of tasks, but their success often hinges on access to large-scale multimodal datasets. While effective in high-resource settings, these models tend to struggle in data-scarce regimes. In this work, we investigate Emergent Communication (EC) as a mechanism to improve sample efficiency in VL-PTMs. We pre-train a Vision-Language Model (VLM) using EC tokens generated through a referential game between two artificial agents. Across three diverse cross-modal matching and reasoning benchmarks, EC pretraining yields substantial gains, improving Visual Referring Expression (VRE) accuracy by 108.6% and Visual Entailment (VE) by 69.6%.

To further validate the effectiveness of EC pretraining, we introduce LLaVA-1.5-EC, a LLaVA variant trained entirely on EC tokens. LLaVA-1.5-EC outperforms strong LVLM baselines, including BLIP-2 (13B), achieving relative gains of 104.23% on VizWiz, 34.8% on GQA, and 10.8% on VQAv2, and top performance on MMBench, a challenging instruction-following benchmark.

These results highlight the transferability and generalization capacity of EC pretraining and underscore the potential of leveraging grounded EC tokens to enhance vision-language reasoning in low-resource settings, especially in settings with limited natural language data. We discuss implications and propose avenues for future research to explore the connections between EC and VL for multimodal understanding and effective human-machine communication.

Contributions

  • Novel Pretraining Framework. We introduce a vision-language pretraining framework that employs Emergent Communication (EC) between agents to generate supervision signals for pretraining. We demonstrate that EC pretraining transfers effectively to diverse downstream multimodal tasks.
  • New Understanding of EC Structure. We empirically show that EC tokens encode structured and compositional semantics that generalize across tasks and modalities, positioning EC as a scalable, annotation-free alternative to natural language supervision in multimodal learning.
  • Theoretical and Empirical Insights. We provide insights into the structure and transferability of emergent language for vision-language pretraining and outline future research opportunities at the intersection of EC, multimodal representation learning, and human-machine communication.

EC-VLM Method

Overview of our EC Pretraining Framework. A speaker-listener pair engages in a referential game, where the speaker generates an Emergent Communication (EC) message to describe a target image, and the listener must identify the correct image among distractors. The resulting EC tokens serve as pretraining supervision for a Vision-Language Model (VLM). This EC-pretrained VLM is then fine-tuned on a range of downstream vision-language tasks, including Visual Entailment, Visual Referring Expression, Image Captioning, and Visual Question Answering. The framework enables transferable visual grounding from synthetic EC messages to natural language tasks.

  1. Referential game

    The speaker describes a target image through EC tokens. The listener uses the message to choose that image among distractors.

  2. EC pretraining

    Image–message pairs provide visually grounded supervision for a vision-language model, without human-written pretraining captions.

  3. Downstream transfer

    The pretrained model is fine-tuned for natural-language tasks, including entailment, referring expressions, captioning, and visual question answering.

Quantitative Results

SNLI-VE accuracy across training-set sizes

Visual entailment accuracy with and without emergent-communication pretraining across training-set sizes.

EC pretraining improves both validation and test accuracy at every training size. With the full training set, EC pretraining reaches 85.3% validation accuracy and 85.01% test accuracy, versus 50.3% and 49.94% for the baseline. The gap to natural-language pretraining narrows as the training set grows.

Base+ EC+ NL
4053.7567.581.259510K50KFullTraining-set sizeValidation accuracy (%)Base: 10K, 50.85Base: 50K, 50.46Base: Full, 50.3+ EC: 10K, 57.3+ EC: 50K, 70.8+ EC: Full, 85.3+ NL: 10K, 81.3+ NL: 50K, 84.9+ NL: Full, 89.05

Instruction-following evaluation

Multimodal instruction-following results, with model size and training data reported alongside benchmark scores.

LLaVA-1.5-EC uses 558K images for EC pretraining and 665K fine-tuning examples. Relative to BLIP-2 (13B), the reported gains are 104.23% on VizWiz, 34.8% on GQA, and 10.8% on VQAv2.

LLaVA-1.5-EC exceeds InstructBLIP (13B) on GQA, VizWiz, and SciQA-IMG, and Qwen-VL on VizWiz (40.03 vs. 35.2), despite Qwen-VL’s much larger pretraining corpus. InstructBLIP retains a higher TextVQA score. Standard LLaVA-1.5 remains stronger on these five instruction-following tasks.

Best scores are bold; second-best scores are underlined.

Instruction-following evaluation
Method LLM Image size Pretrain Finetune VQAv2 GQA VizWiz SciQA IMG TextVQA
BLIP-2 Vicuna-13B 224² 129M — 65.0 41 19.6 61 42.5
InstructBLIP Vicuna-7B 224² 129M 1.2M — 49.2 34.5 60.5 50.1
InstructBLIP Vicuna-13B 224² 129M 1.2M — 49.5 33.4 63.1 50.7
Shikra Vicuna-13B 224² 600K 5.5M 77.4 — — — —
IDEFICS-9B LLaMA-7B 224² 353M 1M 50.9 38.4 35.5 — 25.9
IDEFICS-80B LLaMA-65B 224² 353M 1M 60.0 45.2 36.0 — 30.9
Qwen-VL Qwen-7B 448² 1.4B 50M 78.8 59.3 35.2 67.1 63.8
Qwen-VL-Chat Qwen-7B 448² 1.4B 50M 78.2 57.5 38.9 68.2 61.5
LLaVA-1.5 Vicuna-7B 336² 558K 665K 78.5 62.0 50.0 66.8 58.2
LLaVA-1.5-EC Vicuna-7B 336² 558K 665K 72.03 55.27 40.03 64.45 48.61

MMBench evaluation

Multimodal understanding on MMBench, comparing standard pretraining with emergent-communication pretraining.

LLaVA-1.5-EC leads the listed models with 67.3% on MMBench English and 64.01% on MMBench Chinese. Compared with standard LLaVA-1.5, these are gains of 3.0 and 5.71 percentage points, respectively. Orange bars mark LLaVA-1.5-EC.

MMBench (EN)MMBench (CN)
020406080InstructBLIP-8BInstructBLIP-8B · MMBench (EN): 3636InstructBLIP-8B · MMBench (CN): 23.723.7Qwen-VLQwen-VL · MMBench (EN): 38.238.2Qwen-VL · MMBench (CN): 7.47.4IDEFICS-9BIDEFICS-9B · MMBench (EN): 48.248.2IDEFICS-9B · MMBench (CN): 25.225.2IDEFICS-80BIDEFICS-80B · MMBench (EN): 54.554.5IDEFICS-80B · MMBench (CN): 38.138.1Qwen-VL-ChatQwen-VL-Chat · MMBench (EN): 60.660.6Qwen-VL-Chat · MMBench (CN): 56.756.7LLaVA-7BLLaVA-7B · MMBench (EN): 38.738.7LLaVA-7B · MMBench (CN): 36.436.4LLaVA-1.5-CLIP-7BLLaVA-1.5-CLIP-7B · MMBench (EN): 50.5650.56LLaVA-1.5-CLIP-7B · MMBench (CN): 48.4948.49LLaVA-1.5-7BLLaVA-1.5-7B · MMBench (EN): 64.364.3LLaVA-1.5-7B · MMBench (CN): 58.358.3LLaVA-1.5-EC-7BLLaVA-1.5-EC-7B · MMBench (EN): 67.367.3LLaVA-1.5-EC-7B · MMBench (CN): 64.0164.01Accuracy (%) ↑

Qualitative Results

We conduct an in-depth qualitative analysis to uncover potential patterns in the generated Emergent Communication (EC) text. We show some interesting insights below.

EC token patterns associated with broccoli and food-related image groups.
EC Sequences Exhibiting Semantic Clustering. (a) The repeated occurrence of token 2430 is consistently associated with images containing broccoli. (b) Token 222 functions as a higher-level food category marker. (c) Varying the tokens that follow 222 refines the type of food being described, suggesting contextual disambiguation. (d) The bigram 222 3967 remains food-associated but often appears in scenes involving people interacting with food, such as eating or holding it, indicating compositional encoding of both object and action.
EC token patterns associated with zebra images across different sequence positions.
EC Sequences Reveal Visual Grounding, Compositionality, and Latent Structure. (a) Token 3293 consistently appears in zebra-related images, demonstrating strong visual grounding. (b) A variation in the third token of the trigram suggests fine-grained visual distinctions between zebra scenes, pointing to contextual compositionality. (c) The same trigram from (a) appears at a different sequence position, indicating positional flexibility and implying that EC meaning is carried by token patterns rather than fixed positions — a possible marker of syntactic invariance. Occasional co-occurrence with giraffes suggests token reuse across visually related concepts and hints at fuzzy semantic boundaries between visually similar classes. (d) The trigram from (b), when shifted to position 1, remains strongly correlated with zebra images, reinforcing compositional consistency and semantic robustness.
EC token patterns associated with vehicles and animals, illustrating positional and structural roles.
EC Sequences Exhibit Semantic Specificity and Structural Roles. (a) Token 309 is associated with vehicles, and its position appears to modulate meaning, e.g. at position 2, it tends to refer to motorbikes. (b) The same token in different positions corresponds to trucks, suggesting context-dependent semantic refinement. (c) Token 2512 may denote giraffes, while (d) token 1915 appears to generalize to a broader animal category. Notably, token 3355 occurs across all examples, suggesting a structural or functional role, potentially indicating count, emphasis, or grouping within the sequence.

BibTeX

@article{ogunleye2025ecvlm,
  title={EC-VLM: Emergent Corpus Pre-training Benefits Vision Language Models},
  author={Ogunleye, Makanjuola A. and Vickery, Chase and Lourentzou, Ismini},
  journal={Transactions on Machine Learning Research (TMLR)},
  year={2025}
}
Template acknowledgements

This site is built upon the work of Nerfies, made available under the Creative Commons Attribution-ShareAlike 4.0 International License. We gratefully acknowledge LLaVA for open-sourcing their models and code.