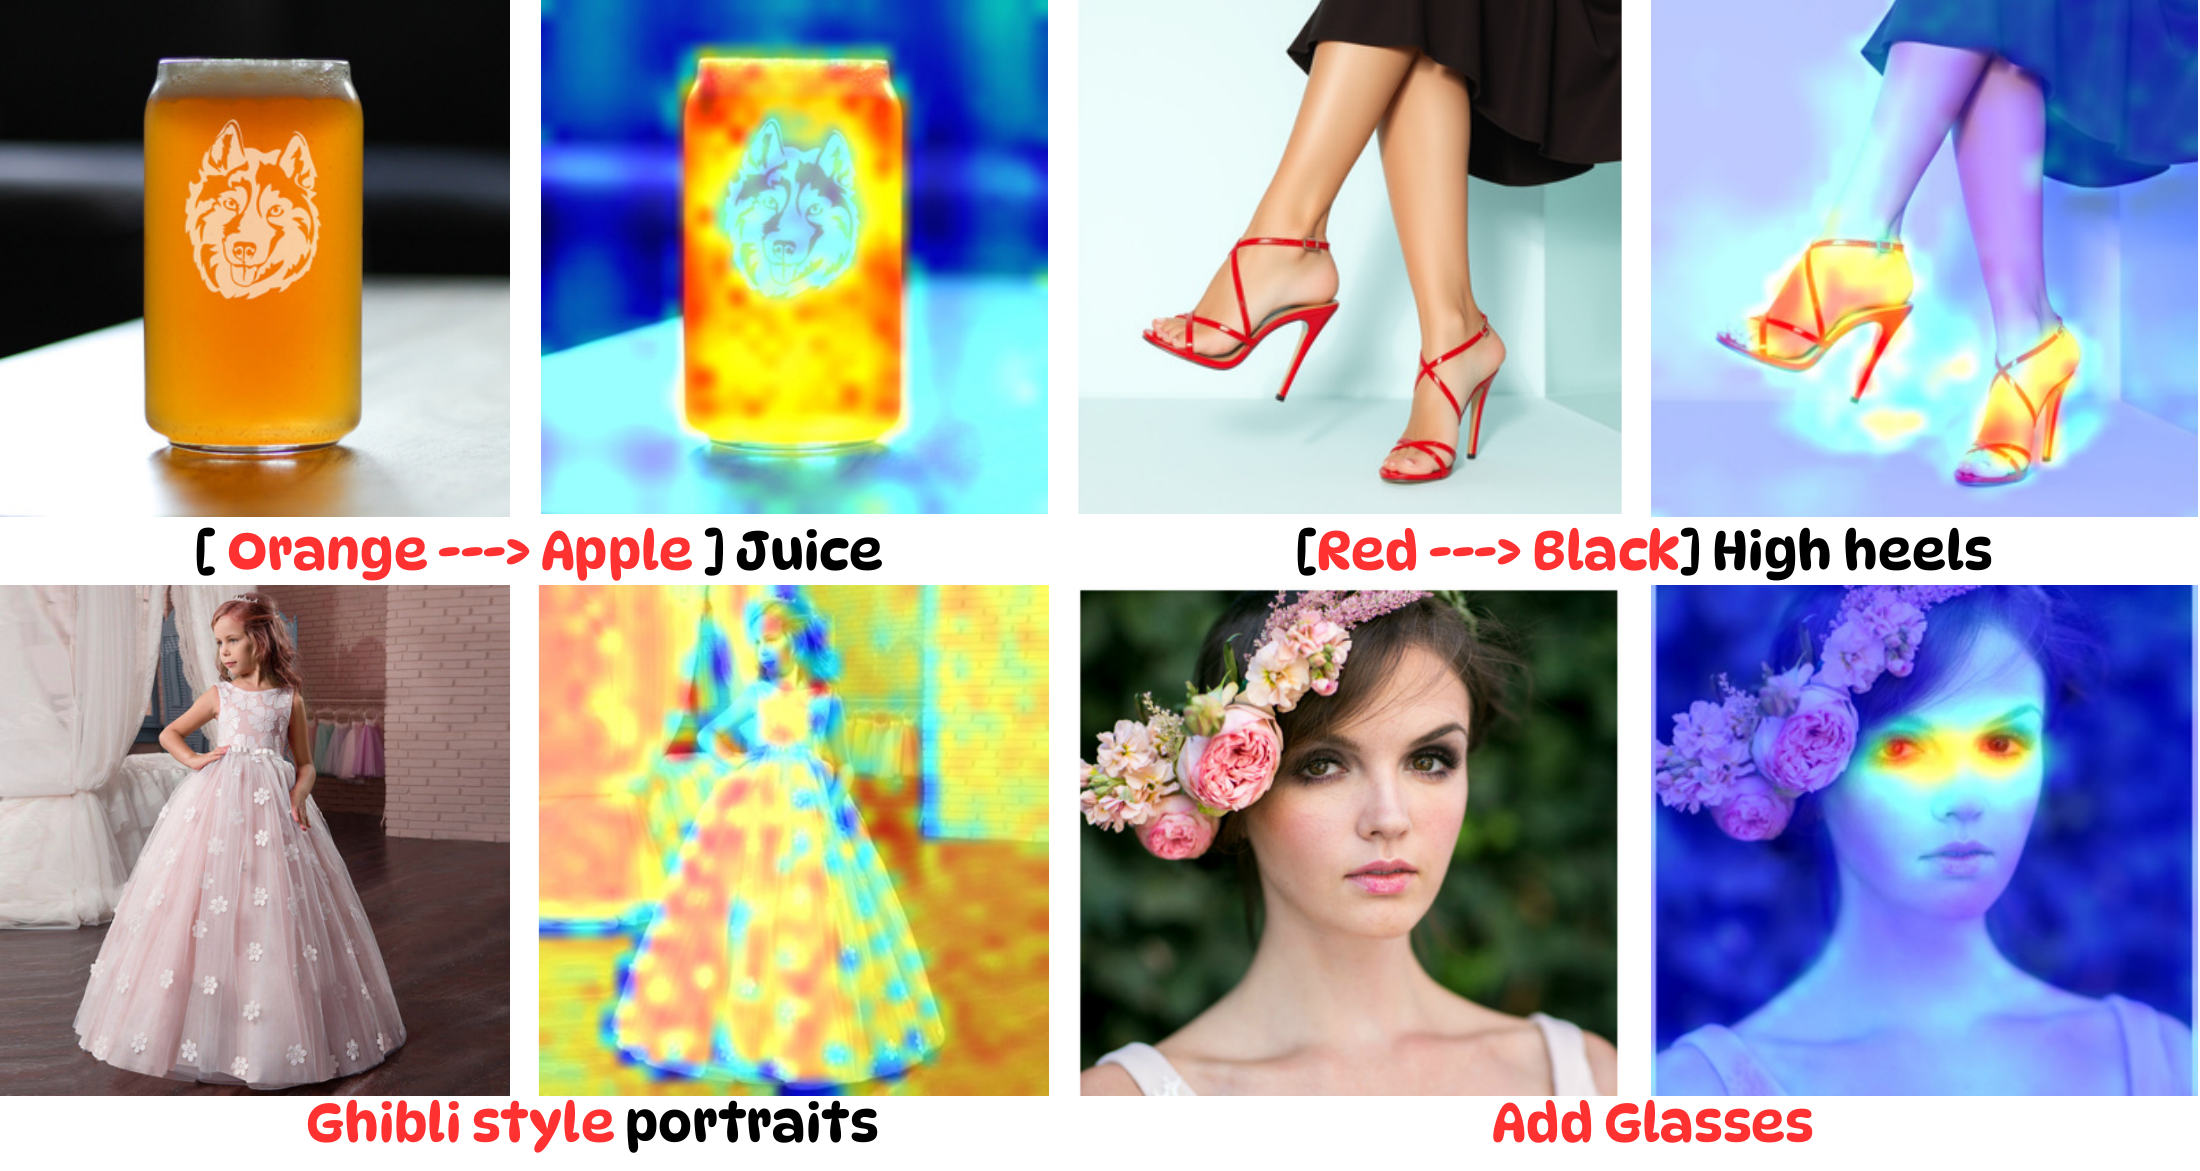
RewardFlow fuses complementary differentiable reward gradients into a multi-reward Langevin sampling update. A prompt-aware policy parses the instruction and adapts reward weights and step sizes throughout sampling. Fine-grained guidance includes a differentiable VQA reward and a SAM2 text-guided object reward to improve attribute correctness and localize edits. A clean-latent KL regularizer tethers sampling to the originating latent, controlling drift while the fused guidance steers generation or editing.
TL;DR
We introduce RewardFlow, a training-free framework for image generation and editing that guides pretrained models with complementary rewards. RewardFlow adapts to each instruction, balancing prompt alignment, visual quality, and localized changes without inversion or model fine-tuning.
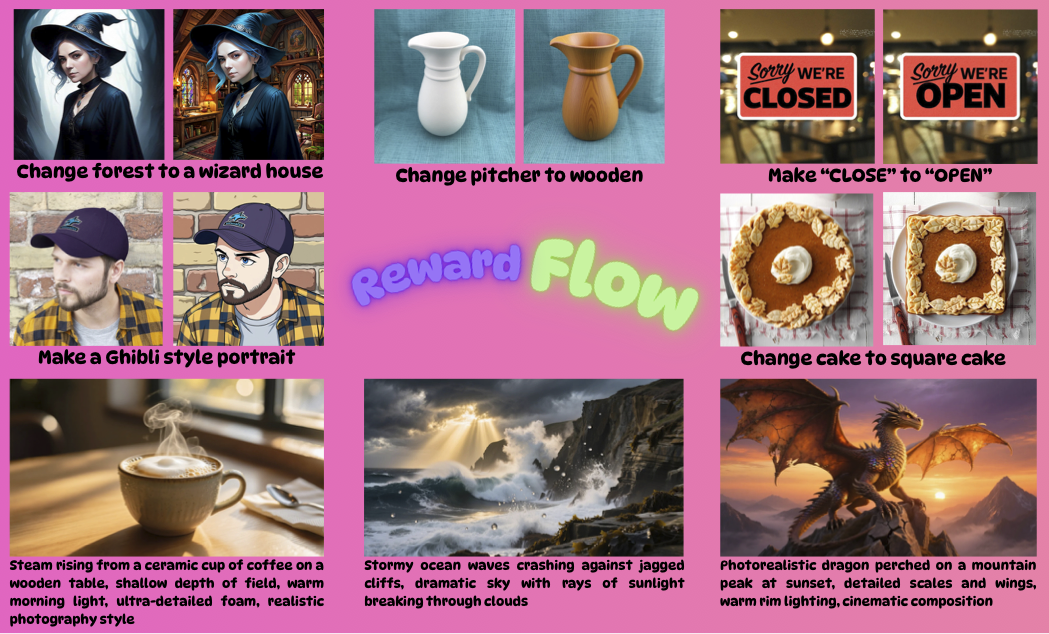
RewardFlow combines semantic, perceptual, regional, object-level, and human-preference signals to steer editing and generation at inference time.
Abstract
We introduce RewardFlow, an inversion-free framework that steers pretrained diffusion and flow-matching models at inference time through multi-reward Langevin dynamics. RewardFlow fuses complementary differentiable rewards for semantic alignment, perceptual fidelity, localized grounding, object consistency, and human preference into a single guidance signal.
To provide fine-grained instruction-level supervision, RewardFlow adds a differentiable VQA-based reward and a SAM2 text-guided object reward, enabling localized edits and preventing semantic leakage outside the target mask. A prompt-aware adaptive policy extracts semantic primitives from the instruction, infers intent, and dynamically modulates reward weights and step sizes throughout sampling.
We further tether sampling to the originating latent via a clean-latent KL regularizer, which anchors the drift produced by the fused reward gradient. Across editing and compositional generation benchmarks, RewardFlow obtains state-of-the-art zero-shot fidelity and alignment without any fine-tuning.
Contributions
- RewardFlow. We introduce a multi-reward-guided Langevin framework that combines semantic, perceptual, regional, object-level, and human-preference signals to enable controllable, inversion-free editing and generation.
- Prompt-aware adaptive policy. Our lightweight policy parses semantic primitives from the instruction, infers edit intent, and dynamically adjusts reward weights and step sizes to balance coarse-to-fine optimization.
- Fine-grained rewards. We design a differentiable VQA reward for attribute-level correctness and a SAM-guided localization reward that penalizes edits leaking outside the region of interest.
- Theoretical grounding. We prove the update corresponds to a valid discretization of a Langevin SDE targeting a prompt-tilted density, giving a sound foundation for stable convergence during reward-guided sampling.
RewardFlow Method
Loading...
Quantitative Results
RewardFlow achieves high edit fidelity and compositional alignment across editing benchmarks.
PIE-Bench image editing
Image editing quality, background preservation, prompt alignment, and sampling cost on PIE-Bench. Standard and four-step settings are reported separately.
| Method | Distance ↓ (×10³) | PSNR ↑ | LPIPS ↓ (×10³) | MSE ↓ (×10⁴) | SSIM ↑ (×10²) | Whole ↑ | Edited ↑ | NFE ↓ | Steps ↓ |
|---|---|---|---|---|---|---|---|---|---|
| Standard inference budgets | |||||||||
| EF | 8.39 | 27.49 | 44.38 | 29.79 | 85.61 | 25.87 | 22.14 | 70 | 50 |
| ProxG | 8.39 | 28.45 | 38.27 | 25.63 | 85.87 | 25.04 | 21.64 | 100 | 50 |
| P2P | 9.58 | 27.72 | 44.98 | 30.02 | 85.01 | 24.94 | 21.57 | 100 | 50 |
| DI | 11.60 | 27.25 | 49.25 | 32.87 | 84.86 | 25.83 | 22.39 | 100 | 50 |
| AREdit | 13.12 | 28.78 | 42.67 | 37.88 | 87.19 | 26.57 | 24.51 | 16 | 30 |
| InfEdit | 13.87 | 28.63 | 39.80 | 33.19 | 86.28 | 25.84 | 22.44 | 12 | 12 |
| TurboEdit | 15.11 | 26.04 | 69.54 | 55.12 | 84.27 | 26.09 | 23.35 | 24 | 12 |
| InstantEdit | 12.57 | 29.63 | 35.27 | 24.57 | 87.40 | 26.06 | 22.73 | 24 | 12 |
| FlowEdit | 11.56 | 28.33 | 43.57 | 37.48 | 86.23 | 26.43 | 23.03 | 33 | 30 |
| FlowChef | 9.67 | 29.03 | 43.11 | 36.67 | 87.44 | 27.05 | 23.09 | 28 | 30 |
| KV-Edit | 8.47 | 29.04 | 43.44 | 35.47 | 86.66 | 28.21 | 23.92 | 27 | 40 |
| Flux+RewardFlow | 7.78 | 31.21 | 40.55 | 26.47 | 89.67 | 29.44 | 26.62 | 43 | 20 |
| QwenImage+RewardFlow | 7.64 | 32.09 | 38.47 | 23.57 | 90.21 | 29.78 | 27.57 | 54 | 25 |
| Four-step inference | |||||||||
| InfEdit | 16.19 | 26.75 | 50.79 | 42.33 | 84.71 | 25.68 | 22.27 | 4 | 4 |
| TurboEdit | 18.57 | 24.59 | 77.53 | 58.48 | 82.64 | 25.70 | 22.30 | 4 | 4 |
| InstantEdit | 17.14 | 27.96 | 44.39 | 34.94 | 86.44 | 26.28 | 22.82 | 8 | 4 |
| Flux+RewardFlow | 13.44 | 29.57 | 40.03 | 29.66 | 88.13 | 27.31 | 24.69 | 6 | 4 |
| QwenImage+RewardFlow | 10.33 | 29.92 | 37.92 | 26.95 | 90.12 | 28.55 | 27.52 | 6 | 4 |
T2I-CompBench compositional generation
Compositional accuracy across attribute binding, object relationships, and complex prompts. Each backbone is compared with ReNO and RewardFlow; higher scores are better.
| Model | Color ↑ | Shape ↑ | Texture ↑ | Spatial ↑ | Non-spatial ↑ | Complex ↑ |
|---|---|---|---|---|---|---|
| SD v1.4 | 0.38 | 0.36 | 0.42 | 0.12 | 0.31 | 0.31 |
| SD v2.1 | 0.51 | 0.42 | 0.49 | 0.13 | 0.31 | 0.34 |
| SDXL | 0.64 | 0.54 | 0.56 | 0.20 | 0.31 | 0.41 |
| PixArt-α | 0.69 | 0.56 | 0.70 | 0.21 | 0.32 | 0.41 |
| DALL-E 2 | 0.57 | 0.55 | 0.64 | 0.13 | 0.30 | 0.37 |
| DALL-E 3 | 0.81 | 0.68 | 0.81 | — | — | — |
| PixArt-α DMD | 0.38 | 0.34 | 0.47 | 0.19 | 0.30 | 0.36 |
| PixArt-α DMD + ReNO | 0.64 | 0.57 | 0.72 | 0.25 | 0.31 | 0.46 |
| PixArt-α DMD + RewardFlow | 0.74 | 0.66 | 0.75 | 0.30 | 0.39 | 0.52 |
| Flux | 0.75 | 0.61 | 0.69 | 0.26 | 0.33 | 0.47 |
| Flux + ReNO | 0.81 | 0.64 | 0.72 | 0.29 | 0.35 | 0.49 |
| Flux + RewardFlow | 0.88 | 0.69 | 0.78 | 0.33 | 0.42 | 0.57 |
| Qwen Image | 0.83 | 0.72 | 0.80 | 0.35 | 0.39 | 0.61 |
| Qwen Image + ReNO | 0.84 | 0.75 | 0.84 | 0.36 | 0.43 | 0.63 |
| Qwen Image + RewardFlow | 0.91 | 0.83 | 0.90 | 0.39 | 0.51 | 0.78 |
Qualitative Results
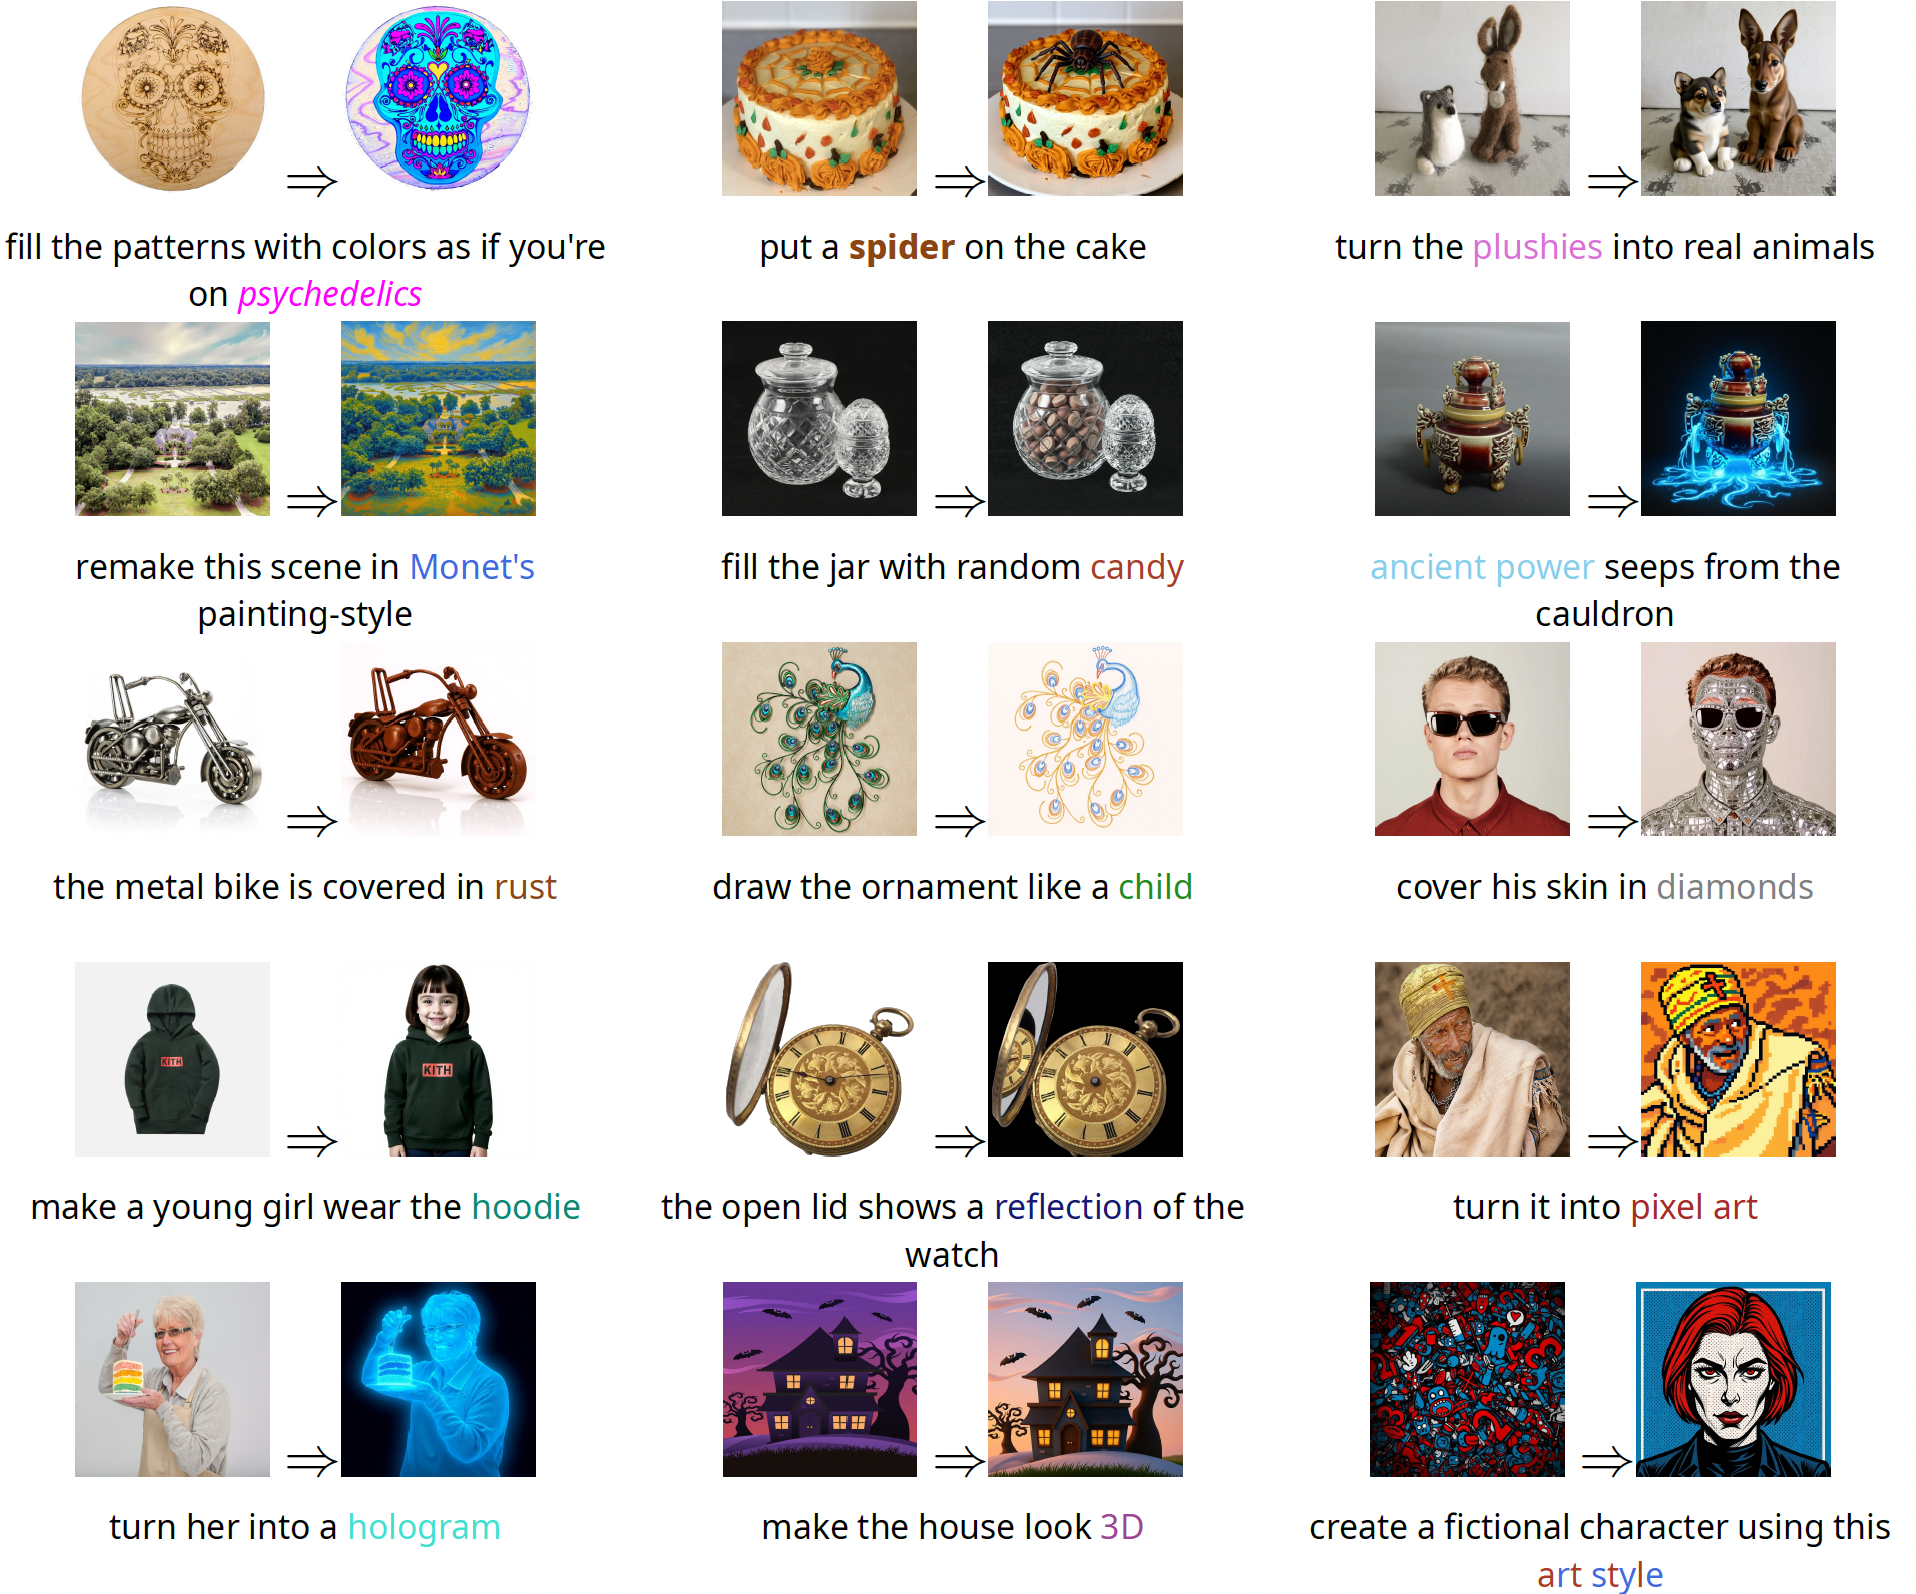
RewardFlow keeps subject identity and layout while enabling localized style/text edits, delivering clean, compositional results without inversion.
Loading...
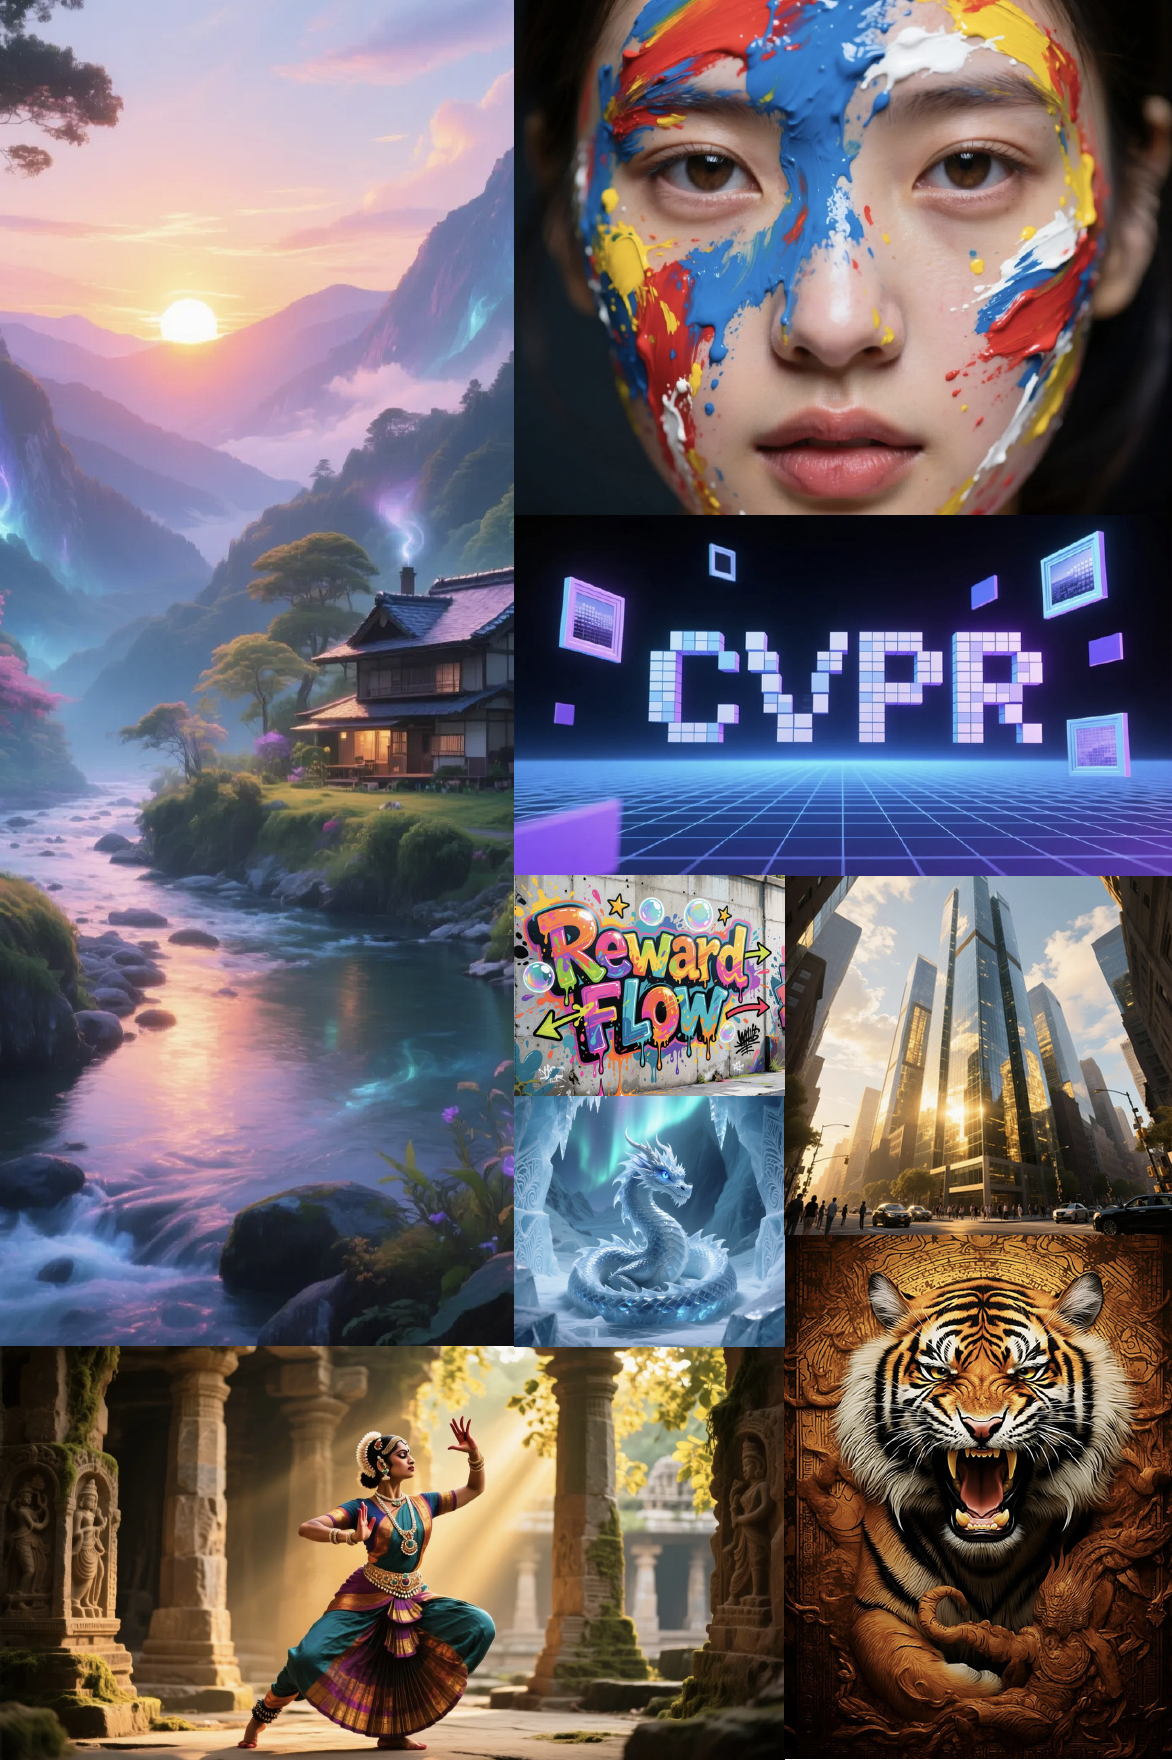
Generation samples guided by multi-reward Langevin dynamics.
Loading...
Additional localized edits.
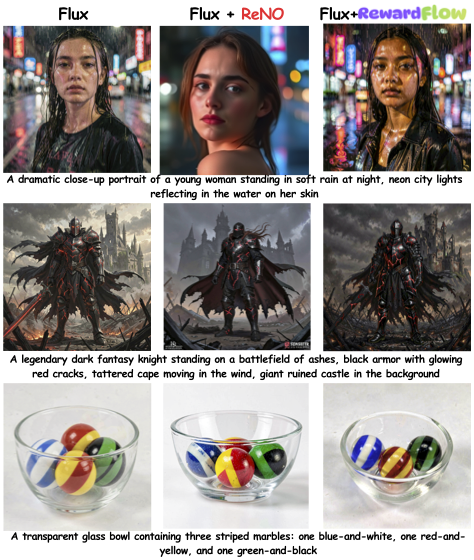
Loading...
Compositional generation vs. baselines.
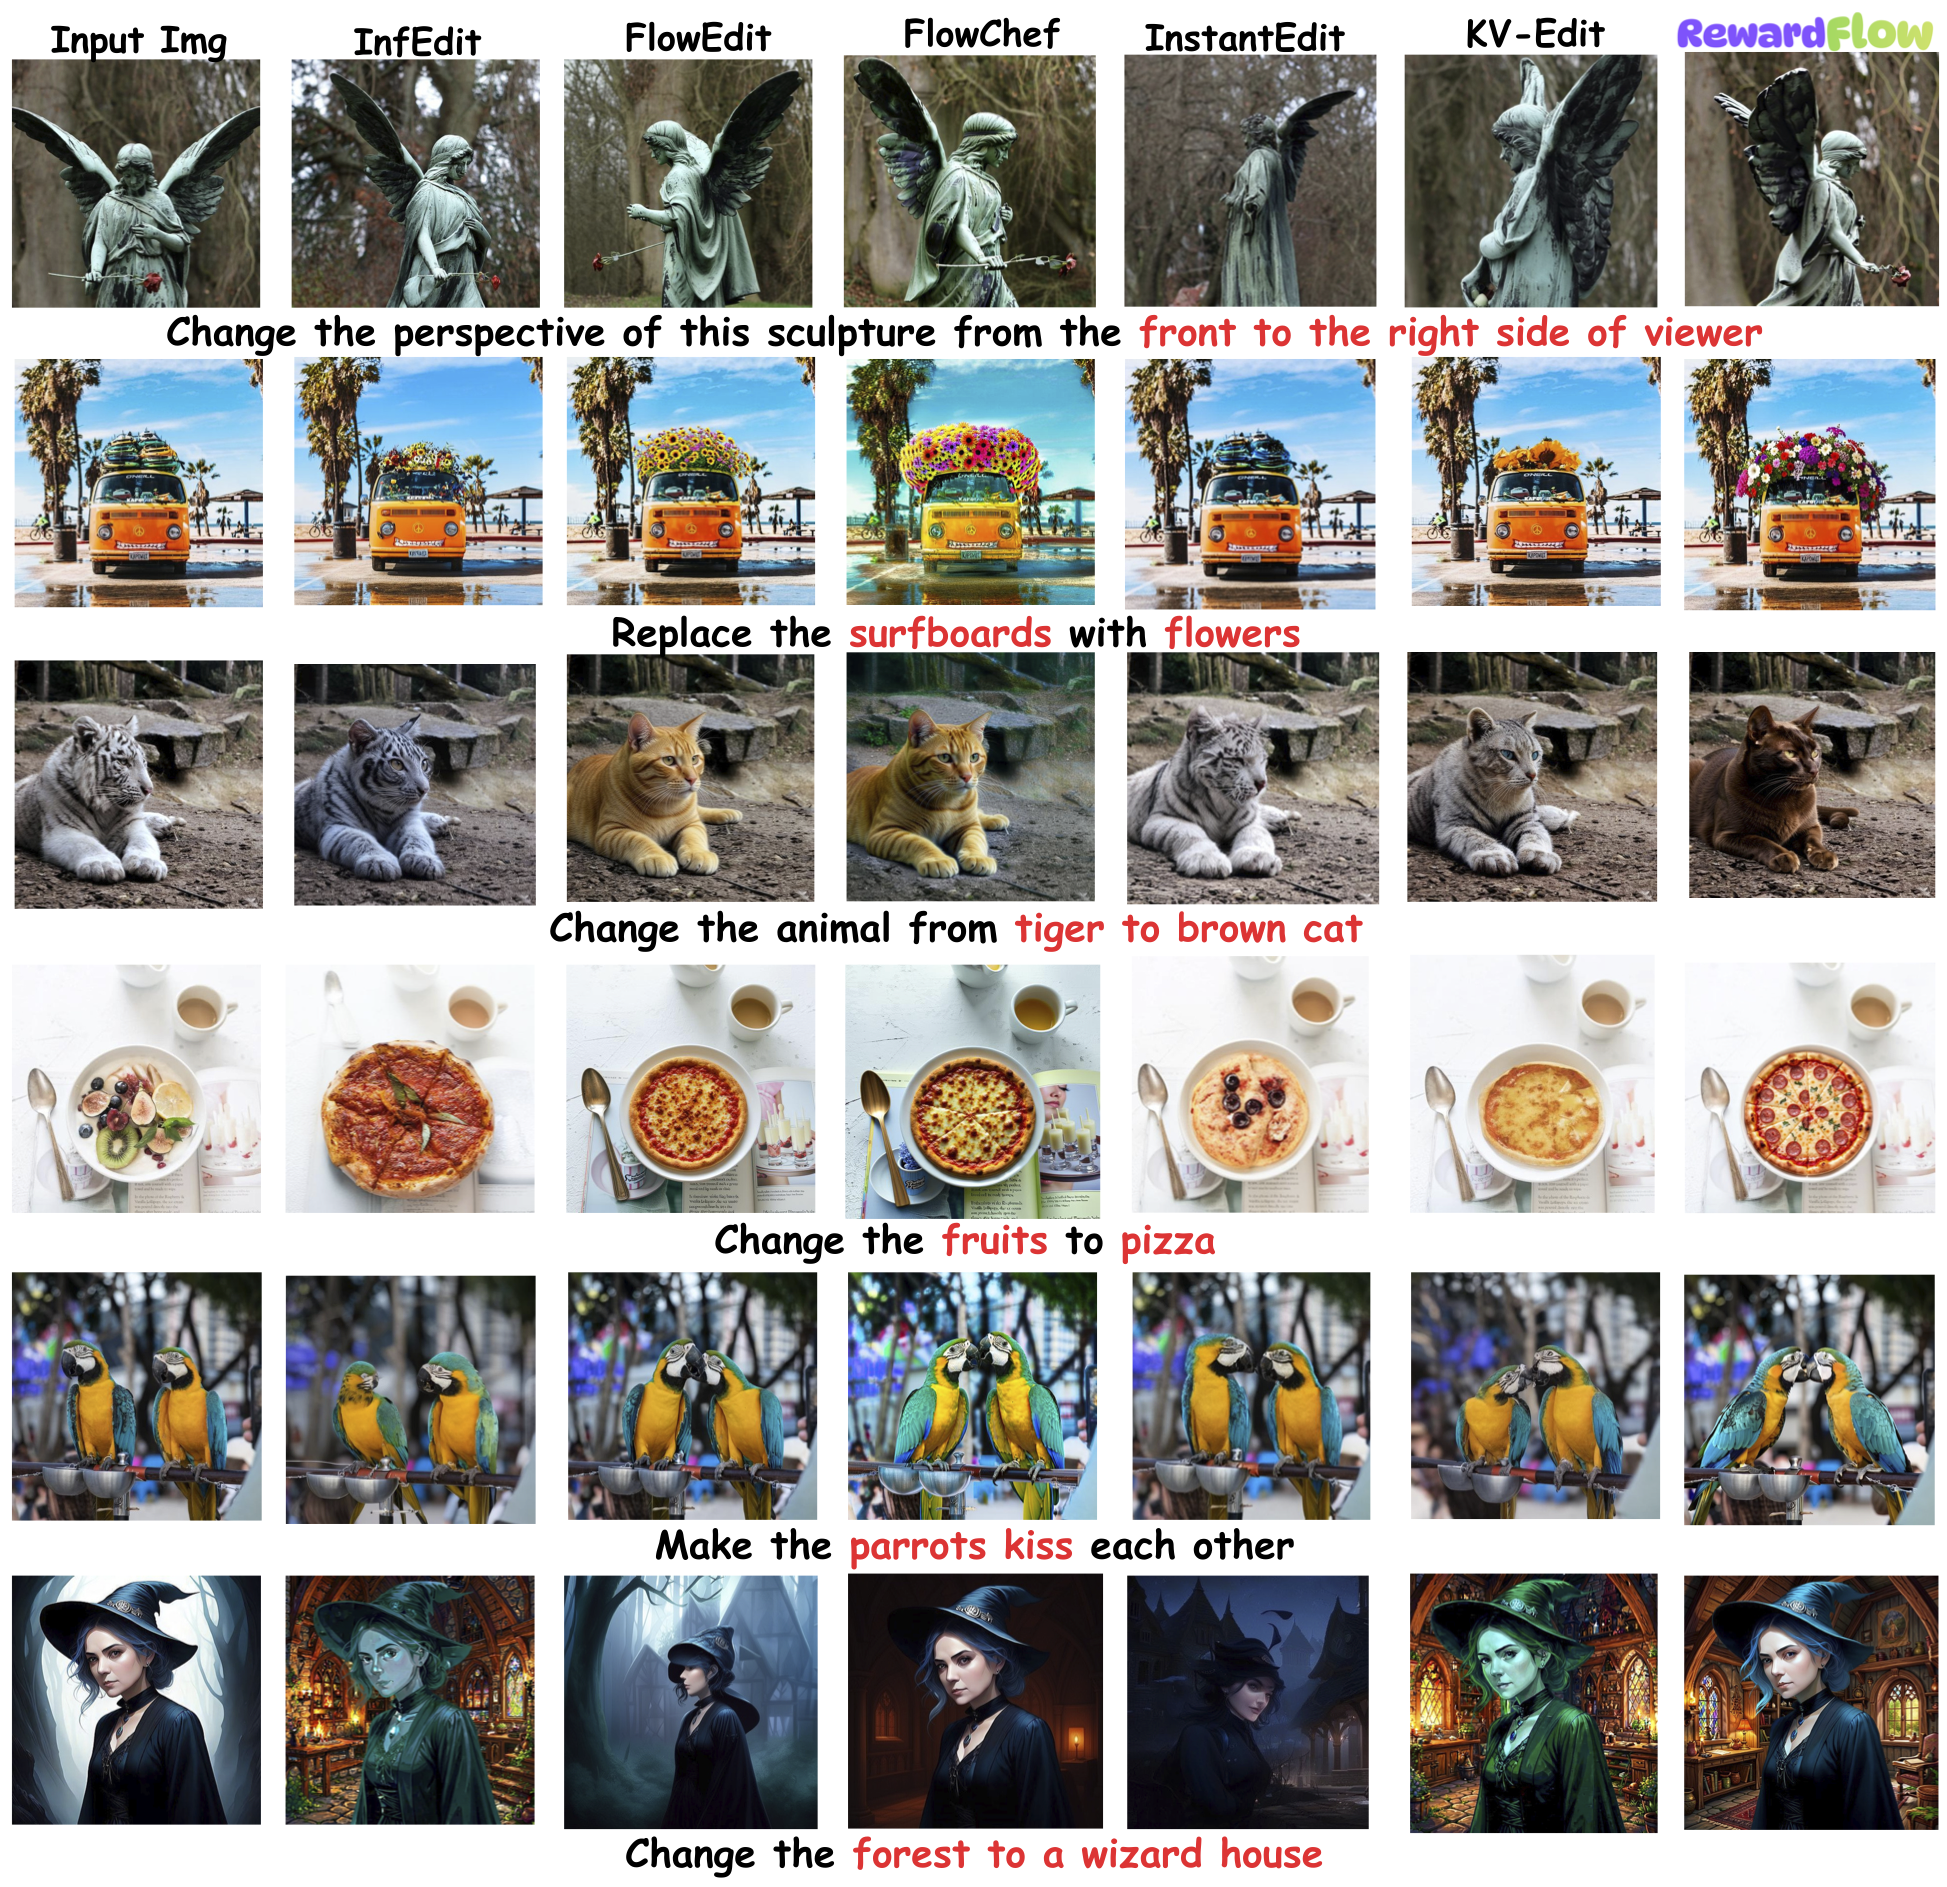
Loading...
Comparison against prior reward-guided techniques highlights improved localization and reduced semantic drift.
BibTeX
@inproceedings{rewardflow2026,
  title={RewardFlow: Generate Images by Optimizing What You Reward},
  author={Susladkar, Onkar and Jang, Dong-Hwan and Prakash, Tushar and Juvekar, Adheesh and Shah, Vedant and Barik, Ayush and Bashir, Nabeel and Wahed, Muntasir and Shrirao, Ritish and Lourentzou, Ismini},
  booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
  year={2026}
}